Why Markdown Is the Default Language for AI and Search Data
▼ Summary
– Markdown is emerging as a new standard for AI infrastructure, replacing JSON as the preferred output format for model interactions.
– Models are trained on vast amounts of Markdown data, allowing them to interpret its structural elements like headers and lists as semantic signals.
– Using Markdown reduces token overhead compared to nested JSON, leading to more efficient context window usage and lower inference costs.
– Major providers like OpenAI explicitly recommend Markdown in prompt engineering documentation to improve model compliance and readability.
– API and data providers are adopting Markdown variants to simplify parsing for agents and align with how models naturally process information.
Markdown is rapidly establishing itself as the primary language for AI infrastructure, signaling a decisive break from the long-standing dominance of JSON. While JavaScript Object Notation has served as the universal interchange format for decades, major model providers are increasingly adopting Markdown as the default output for any data that needs to be ingested by large language models. This transition is not merely aesthetic; it reflects the fundamental mechanics of how models are trained, how chat interfaces render content, and how developers manage token efficiency and context windows.
Alignment with Model Training and Rendering
The shift toward Markdown is rooted in the training data of modern AI systems. Large language models have been exposed to vast quantities of documentation, README files, technical blogs, and forum threads, all of which heavily utilize Markdown syntax. Consequently, models interpret headers, lists, tables, and code fences as semantic signals rather than noise. This fluency creates a natural input-output loop: when a model outputs Markdown, front-end interfaces can render it cleanly without additional transformation, and when a model ingests Markdown, it receives data in a structure that mirrors its training distribution.
From a technical standpoint, Markdown offers superior token efficiency compared to dense, nested JSON structures. By stripping away structural overhead while preserving the informational payload, Markdown allows AI agents to fit more relevant content into limited context windows. This efficiency translates directly into lower inference costs and improved performance, making it an attractive alternative for applications where token count is a critical constraint.
Industry Adoption and Best Practices
This trend is already codified in guidance from leading model providers. OpenAI’s prompt engineering documentation explicitly recommends structuring developer messages using Markdown headers, bullet points, and tables to enhance model compliance and readability. The guidance suggests using specific formatting conventions, such as ‘##’ for major sections and inline backticks for code, to optimize interactions. Third-party prompting guides echo this pattern, noting that Markdown is more naturally understood by models trained on documentation-heavy corpora, particularly newer GPT-5 series models.
Infrastructure providers are also aligning with this standard. API services are moving away from JSON-only outputs to offer Markdown variants optimized for LLM consumption. The goal remains consistent: reduce token bloat, simplify parsing for autonomous agents, and ensure that data presentation aligns with how models are prompted and how answers are displayed.
SerpApi’s Implementation and Token Savings
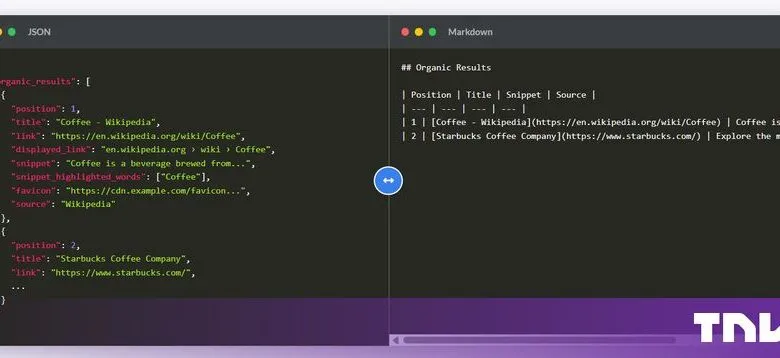
A prominent example of this shift is SerpApi, a search-data API provider serving Fortune 500 companies and researchers. The company recently launched Markdown output across all 100+ of its APIs at no extra cost, allowing developers to request search results in a token-light format instead of JSON. This feature requires no new endpoints; developers can specify the format via a query parameter, route extension, or header on existing integrations.
The impact on token usage is significant. In benchmarks comparing responses for a single Google search for “coffee,” JSON payloads required 24,723 tokens, whereas Markdown versions used only 6,435 tokens, representing a 74% reduction. When combined with field filtering, the token count dropped further to 1,298. Across its various APIs, SerpApi reports average savings of roughly 50%, with some endpoints seeing reductions of up to 90%. These figures are particularly important because search results are among the noisiest, most nested payloads that agents ingest. JSON responses often carry redirect links, favicons, tracking parameters, and deeply nested metadata that models do not need to reason over. Markdown preserves core information like titles, snippets, links, prices, and ratings in structured tables and lists while automatically stripping internal tracking noise.
Developers can access this format by adding ‘output=md’ to the query string, calling the ‘/search.md’ route, or setting an ‘Accept: text/markdown’ header. Responses include YAML frontmatter for metadata and native inline links, designed to be dropped directly into prompts or agent memory.
The Future of Machine-Readable Data
As web content becomes increasingly consumed by agents rather than humans, the infrastructure layer will continue to optimize for machine readability over human-friendly nesting. JSON remains essential for programmatic manipulation and strict schema enforcement, but for the context ingestion phase of AI workflows, Markdown is emerging as the new default.
In the coming months, more data providers are expected to offer Markdown variants for search, e-commerce, maps, and content APIs, where token efficiency has an immediate impact on cost and performance. Prompt templates and agent frameworks are likely to standardize on Markdown sections, tables, and lists as the canonical way to present retrieved context to models. Tooling will evolve around measuring and minimizing token footprint, with Markdown serving as a primary lever. For developers building with LLMs, preferring formats that match how models are trained and how they output is becoming a necessity. Markdown is no longer just a documentation tool; it is becoming the new lingua franca between search data and AI models.
(Source: The Next Web)