
Google has updated its documentation to clarify that the Mediapartners-Google crawler serves a broader range of advertising products beyond just…
Read More »robots.txt
Entity category: technology
Cloudflare’s new Disallow AI Training setting allows site owners to block AI model development crawlers while preserving access for major…
Read More »
A Common Crawl analysis reveals that llms.txt adoption is largely driven by automation, with 68% of files generated by plugins…
Read More »
The Seattle Times and Newsday have sued OpenAI and Microsoft for systematically scraping news content while bypassing paywalls, arguing that…
Read More »
Organizations can block AI crawlers using either robots.txt directives or server-level controls, with the choice depending on specific infrastructure and…
Read More »
AI coding agents like Claude and Codex are automatically executing malicious code by processing links found in `llms.txt` files on…
Read More »
OpenAI’s GPTBot and related crawlers are accessing domains that have blocked them via robots.txt, with OpenAI’s documentation confirming that some…
Read More »
Google introduced a Search Console setting allowing site owners to exclude their content from AI Overviews, AI Mode, and Discover's…
Read More »
A Reddit user discovered that Google was indexing spam-filled search results on a Shopify store despite a robots.txt block, because…
Read More »
SEO changelogs provide enterprise teams with visibility, accountability, and cross-team awareness of website changes that impact search performance, preventing costly…
Read More »
For two decades, SEO guidance was portable across search engines due to shared standards like Sitemaps, Schema.org, and robots.txt, built…
Read More »
AI-assisted coding like "vibe coding" can quickly generate functional websites, but it does not automatically achieve SEO success without clear,…
Read More »
Google is updating its robots.txt documentation to list the top 10-15 most common unsupported rules, based on real-world data collected…
Read More »
Core SEO fundamentals like HTTPS and title tags are improving due to automation by content management systems and plugins, creating…
Read More »
Anthropic has updated its web crawler policy to give website owners granular control, distinguishing between three separate bots (ClaudeBot, Claude-SearchBot,…
Read More »
Autonomous AI bots now constitute a significant and growing portion of web traffic, fundamentally shifting the internet from a human-centric…
Read More »
The robots.txt file is a fundamental technical SEO tool that instructs web crawlers which website areas they can or cannot…
Read More »
Perplexity denies bypassing web protocols, stating its AI retrieves data only in response to user queries, unlike traditional crawlers that…
Read More »
Cloudflare accused AI startup Perplexity of bypassing website restrictions to scrape data, allegedly disguising its bots by altering user-agent identifiers…
Read More »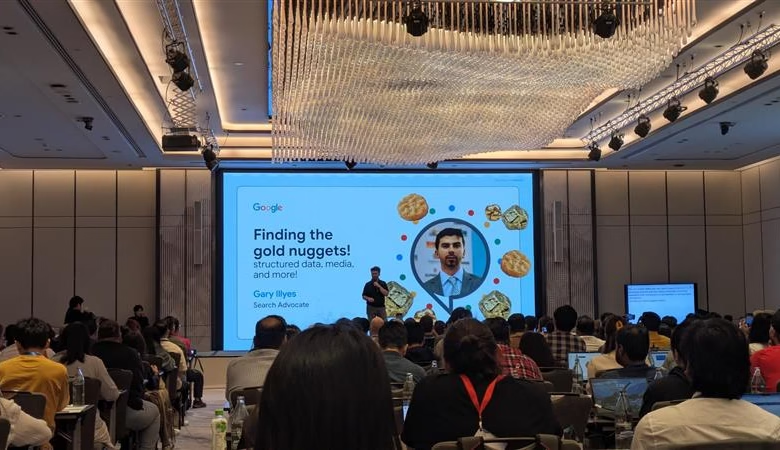
Google Search Central Live APAC 2025 highlighted key insights on indexing, content optimization, and ranking signals, clarifying misconceptions and offering…
Read More »