Customization: The Next Frontier for Decision Models
▼ Summary
– Decision models, which prioritize fast and cheap binary choices over generative output, are gaining significant traction in the AI ecosystem.
– TypeSafe’s Jev model has dominated usage metrics, prompting major tech companies like Amazon and Microsoft to rapidly develop their own decision models.
– Microsoft CEO Satya Nadella announced the immediate rollout of Microsoft-Decision-1.1 on Azure, reflecting industry-wide adoption of this technology.
– Startups like Sqwish are raising capital and offering tools that allow customers to fine-tune decision models using their own production data.
– Success in this category relies heavily on synthetic data calibration and practical performance benchmarks rather than standardized ranking systems.
Decision models have rapidly evolved from a novel concept into a critical infrastructure component of the modern AI stack. By October, these specialized systems accounted for more than one in four requests on Vercel’s AI model router, surpassing traditional large language models (LLMs). This surge occurred just a month after the category was first introduced, highlighting an immediate and substantial shift in how computational resources are allocated. Unlike standard LLMs that generate text tokens, decision models leverage general intelligence to select from predefined options with high speed and low cost. Crucially, they also provide a confidence metric for their choices, making them ideal for production environments where rapid execution outweighs the need for verbose reasoning.
The market leader in this space is TypeSafe, which achieved a valuation of $7.5 billion following the release of its Jev family of models. Metrics from services like OpenRouter indicate that TypeSafe’s models handled over 1.5 billion queries last week alone, cementing their dominance. However, the barrier to entry remains low. The ease of creating decision models led to a proliferation of options, with dozens released shortly after Jev’s debut. An Amazon engineer reportedly built a functional version in a single weekend, prompting every major hyperscaler to develop their own variants. On Tuesday, Microsoft CEO Satya Nadella announced the immediate wide-scale rollout of Microsoft-Decision-1.1 on Azure, signaling intense competition among tech giants.
The Role of Data and Synthetic Training
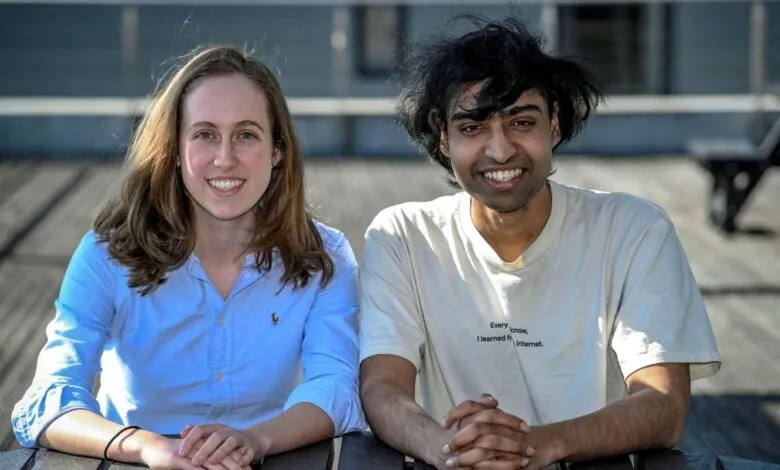
Success in this sector hinges heavily on data quality rather than raw scale. TypeSafe CEO Diogo Almeida noted that the primary challenge in building Jev was fine-tuning its judgment through statistically adjusted synthetic data. Sqwish, a U. K.-based startup that recently secured a $3 million pre-seed round, approaches this differently. Co-founders Ushnish Sengupta and Federica Freddi, who met as Cambridge graduate students, pivoted their small LLM architecture to serve as a decision model upon seeing the potential of Jev. While Sqwish also utilizes synthetic data, its unique value proposition lies in post-training tools that allow customers to integrate their own proprietary data to refine the model’s accuracy.
This approach creates a moat against commoditization. As Sengupta explained:
> “What makes us not a commodity, I think, is the fact that we are offering our customers the same power…they can keep uploading their production data, and just the same way that we trained our models, their models can also keep getting better at the tasks that they care about.”
For startups like Sqwish, the ability to continuously improve models using client-specific data offers a competitive edge against larger entities that may lack such tailored feedback loops.
Benchmarking vs. Real-World Performance
Evaluating the efficacy of decision models presents unique challenges. While Sqwish’s kettei fat model has shown promise on specific benchmarks, industry builders argue that real-world performance is the true test. Developers can easily swap one model for another to observe contextual differences, suggesting that static metrics may not fully capture utility. Sengupta emphasized that initial testing serves as a gateway to long-term adoption:
> “The benchmark is more of an invitation to try the model out, and then the continual tuning is the reason why they should stick to us.”
Microsoft aligns with this perspective. Achint Srivastava, the engineering vice president who led the development of Microsoft-Decision-1.1, warned against over-reliance on standardized tests. He stated:
> “What we see is that ‘benchmaxed’ models fall flat under real enterprise usage very quickly. Our testing underscores just how challenging it is to deliver accuracy, reliability, speed and cost efficiency in a single model. Microsoft-Decision-1.1 and Jev are among the few that perform strongly across all four dimensions, even when evaluated on ‘held out’ or unseen benchmarks reflective of real use cases.”
Future Integration of Intelligence Systems
Despite the current hype, some founders view decision models as part of a broader architectural evolution rather than a standalone solution. Freddi predicts a future where System One intelligence, represented by fast decision models, operates in tandem with System Two intelligence, such as slower but more capable frontier LLMs. This symbiotic relationship could redefine market dynamics.
Freddi highlighted the disparity in strategic focus between startups and incumbents:
> “Even in that future, System One is maybe a $10 billion, $50 billion [opportunity], and OpenAI is doing this IPO with you know $1 trillion, $2 trillion market value in mind. This is all we care about; whereas for them, this is just a side project.”
This distinction suggests that while hyperscalers may treat decision models as supplementary tools, specialized firms are dedicating their core resources to mastering this niche, potentially carving out significant value in the evolving AI ecosystem.
(Source: TechCrunch)